raster column type to Apache Iceberg tables, so you can store and query raster data in tables. This tutorial describes how to use raster data type and raster functions in WherobotsDB for manipulating raster data.
In-DB raster vs. Out-DB raster
WherobotsDB supports two types of raster data: In-DB raster and Out-DB raster. In-DB raster stores the complete raster data in WherobotsDB. Out-DB rasters only holds the geo-referencing information of the raster, as well as the path to the actual raster data. The actual raster data is stored in remote storage, such as S3. Out-DB rasters are useful when the raster data is too large to be stored in parquet files, or when the raster data is already stored in some remote storage.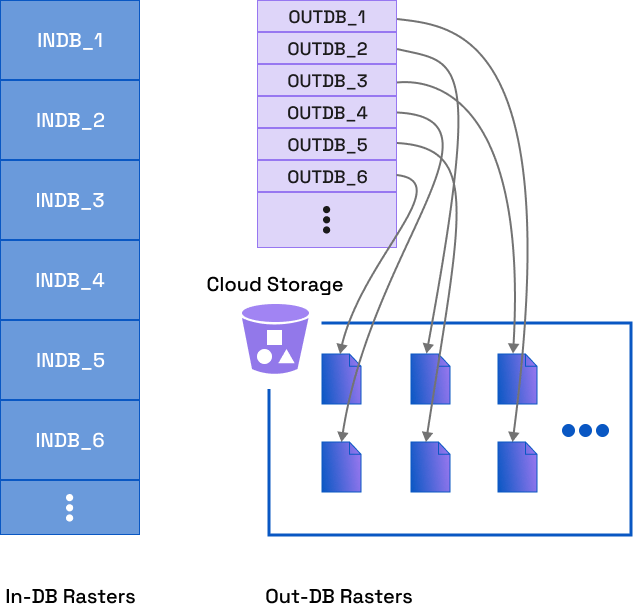
RS_Metadata, RS_GeoReference, and RS_SRID. Functions that read band values, such as RS_Value, RS_MapAlgebra, and RS_Resample, must read the raster file from remote storage, so they run slower on out-DB rasters than on in-DB rasters. To speed up those reads, see Tune out-DB raster reads.
Store only small rasters as in-DB rasters. In-DB rasters are stored in the table’s data files, so small ones, such as preprocessed chips, are read with high throughput by downstream applications, including machine learning tasks powered by RasterFlow. For instance, the 64x64 labeled chips in the EuroSAT dataset load faster as in-DB rasters. Large in-DB rasters make processing prone to out-of-memory errors, because the entire raster is loaded into memory when it is read from the data files. Store large rasters as out-DB rasters so they are loaded lazily; tasks that require shuffles, such as repartitioning and sorting, also run faster on out-DB rasters.
Create an Out-DB Raster type column
Out-DB Rasters has the same data type with In-DB Rasters, they are all represented as theraster column type in tables and can be loaded as RasterUDT objects in Sedona. If user has a table containing a raster column, it can have both In-DB and Out-DB rasters
in that column.
Load raster files with the raster data source
Use the raster data source to load raster files. It reads GeoTIFF and Arc Info ASCII Grid (.asc) files as out-db rasters, splits each file into tiles as it reads it, and spreads the tiles across the cluster.
- Python
- Scala
- Java
x and y and the name of the source file:
raster data source, see Loading raster using the raster loader.
The
raster data source keeps the pixel values exactly as stored in the file. Set option("autoRescale", "true") to apply the GeoTIFF’s per-band scale and offset while reading. See Band values, scale, and offset.Load whole files, directories, or a list of files
To load each file as one out-db raster instead of tiles, setretile to false. The EuroSAT sample files are small and aren’t internally tiled, so the examples in the rest of this section load them this way:
- Python
- Scala
- Java
/ loads every .tif and .tiff file under that directory, including its subdirectories:
- Python
- Scala
- Java
- Python
- Scala
- Java
Retrieve the path of Out-DB Rasters
The rasters path of out-db rasters can be retrieved usingRS_BandPath function. It will give the path of the raster file in remote storage. If the argument is an in-db raster, RS_BandPath will return NULL.
- Python
- Scala
- Java
Divide and explode Out-DB Rasters
Theraster data source tiles files as it loads them. To split rasters loaded with retile set to false, such as df above, into tiles, use the RS_TileExplode function:
- Python
- Scala
- Java
RS_TileExplode produces are also Out-DB rasters as long as the input raster is an Out-DB raster. These tiles reference different parts of the same raster file in remote storage, so they are very cheap to create.
- Python
- Scala
- Java
Load out-db rasters from a STAC catalog
The STAC reader returns one row for each STAC item and adds an out-db raster to each asset, inassets['<asset name>'].rast, so the rasters of a STAC catalog need no separate loading step. The following example reads two items of the Sentinel-2 Collection 1 Level-2A collection on Earth Search and selects the raster of each item’s red asset:
- Python
- Scala
- Java
Supported Out-DB Storages
WherobotsDB supports out-db rasters on any storage that Hadoop supports, as long as the storage has an implementation oforg.apache.hadoop.fs.FileSystem on the classpath of the Wherobots Cloud. In the above examples, we accessed out-db rasters stored on S3 using the S3A file system provided by Hadoop AWS. Following is a list of storages that are tested on Wherobots Cloud:
Create an In-DB Raster type column
All raster operations in Spatial SQL require Raster type objects. Therefore, this should be the next step after loading the data.Load binary raster data
Assume we have a single raster data file called rasterData.tiff, at Path. Use the following code to load the data and create a WherobotsDB Dataframe.- Python
- Scala
- Java
The above code works too for loading multiple raster data files. if the raster files are in separate directories and the option also makes sure that only
.tif or .tiff files are being loaded.- Python
- Scala
- Java
Recursive file lookup will also work similarly for raster datasets in .asc file formats.
From Geotiff
From Arc Grid
The raster data is loaded the same way astiff file, but the raster data is stored with the extension .asc, ASCII format. The following code creates a Raster type objects from binary data:
Raster’s metadata
WherobotsDB has a function to get the metadata for the raster, and also a function to get the world file of the raster.Metadata
This function will return an array of metadata, it will have all the necessary information about the raster, Please refer to RS_MetaData.World File
There are two kinds of georeferences, GDAL and ESRI seen in world files. For more information please refer to RS_GeoReference.Tune out-DB raster reads
Functions that read band values fetch out-DB raster data from remote storage. WherobotsDB caches those reads, and the parameters below control the cache. Set them when you create the Spark session; they can’t be changed afterward. For defaults and the full list, see Raster parameters.Out-DB raster cache
If an out-DB raster is read from the same path more than once, it may hit the cache instead of being fetched from remote storage again. The cache is per executor core: cores in the same executor don’t share a cache, because it is implemented as thread-local variables.spark.wherobots.raster.outdb.pool.size sets the number of rasters in each cache (default 100). When a cache is full, the least recently used raster is evicted. The cache is stored on local disk, in the directory set by spark.wherobots.raster.outdb.cache.dir (default /data/outdb-cache), which is also where the Spark block manager stores shuffled data. If disk space runs short, lower the pool size or use a larger EBS volume. If your out-DB rasters are rarely read more than once, set the pool size to 0 to disable the cache.
The pool size should be larger than the number of distinct out-DB raster paths in each partition. Otherwise, the cache thrashes and won’t be effective.
Read-ahead size
The cache doesn’t download an entire out-DB raster at once. It caches only the parts of the raster file that are read. For example,RS_Value(rast, pt) fetches and caches only the part of the file that contains the tile with pt. spark.wherobots.raster.outdb.readahead sets the size of each read (default 64k):
- For functions that read the entire raster file, such as
RS_MapAlgebraandRS_Count, a larger read-ahead size, for example4m, improves performance. - For functions that read a small portion of the raster file, such as
RS_Value, a smaller read-ahead size performs better, because the extra data read ahead isn’t reused. The exception is manyRS_Valuecalls that together hit most of the tiles of an out-DB raster: the extra data is then reused by later calls, so a larger read-ahead size helps.
Improve the cache hit rate
Because each executor core has its own cache, a raster read on different cores is cached more than once. Two practices make cache hits more likely. In both examples,RS_TileExplode splits the 13-band EuroSAT sample files into 32x32 out-DB tiles, and RS_MapAlgebra combines the first two bands of each tile.
Cache the DataFrame. Cache the DataFrame that contains out-DB rasters before running raster operations on it. Spark is then more likely to schedule the operations on the same executor cores, so cached rasters are reused.
- Python
- Scala
- Java
RS_BandPath(rast) before processing. The performance gain usually outweighs the cost of the sort.
- Python
- Scala
- Java
Use Cloud Optimized GeoTIFF
Use Cloud Optimized GeoTIFF (COG) files for out-DB rasters. COG is optimized for reading from remote storage such as S3:- A COG keeps its Image File Directory (IFD) in a contiguous block at the beginning of the file, so WherobotsDB reads the entire IFD without seeking to discrete locations in the file. This matters for remote storage, where many small discrete reads are much slower than a single large read.
- A COG organizes band data in properly sized square tiles, such as 256x256. Square tiles are more likely than strip tiles, such as 10000x1, to be reused by most raster operations, especially
RS_TileandRS_TileExplode. WherobotsDB also reads GeoTIFFs with strip tiles, but performance may be worse than with COG files.
gdalinfo and look at the Band 1 section of the output. The tile size is 256x256 in this example:
gdal_translate with the COG output driver (-of COG):
-co COMPRESS=DEFLATE or -co COMPRESS=LZW to set the compression method. See the GDAL COG documentation for more information.