

org_catalog; replace it with the name of the catalog you write to.
How spatial filter push-down works
WherobotsDB collects and records the spatial statistics of data files when writing data to the table. The spatial statistics includes the minimum bounding rectangle (MBR) of the geometries in the data file. When a spatial query is issued, WherobotsDB will first check the MBR of the geometries in the data file against the spatial filter. If the MBR doesn’t intersect with the spatial filter, WherobotsDB will skip reading the data file. The following figure shows how spatial filter push-down works. The MBRs of each data file are kept in the table metadata for pruning data files. The query window shown as the red rectangle only overlaps with the bounding box of datafile-2.parquet and datafile-4.parquet, so WherobotsDB can safely skip scanning datafile-1.parquet and datafile-3.parquet, reducing the IO cost and answer the query faster.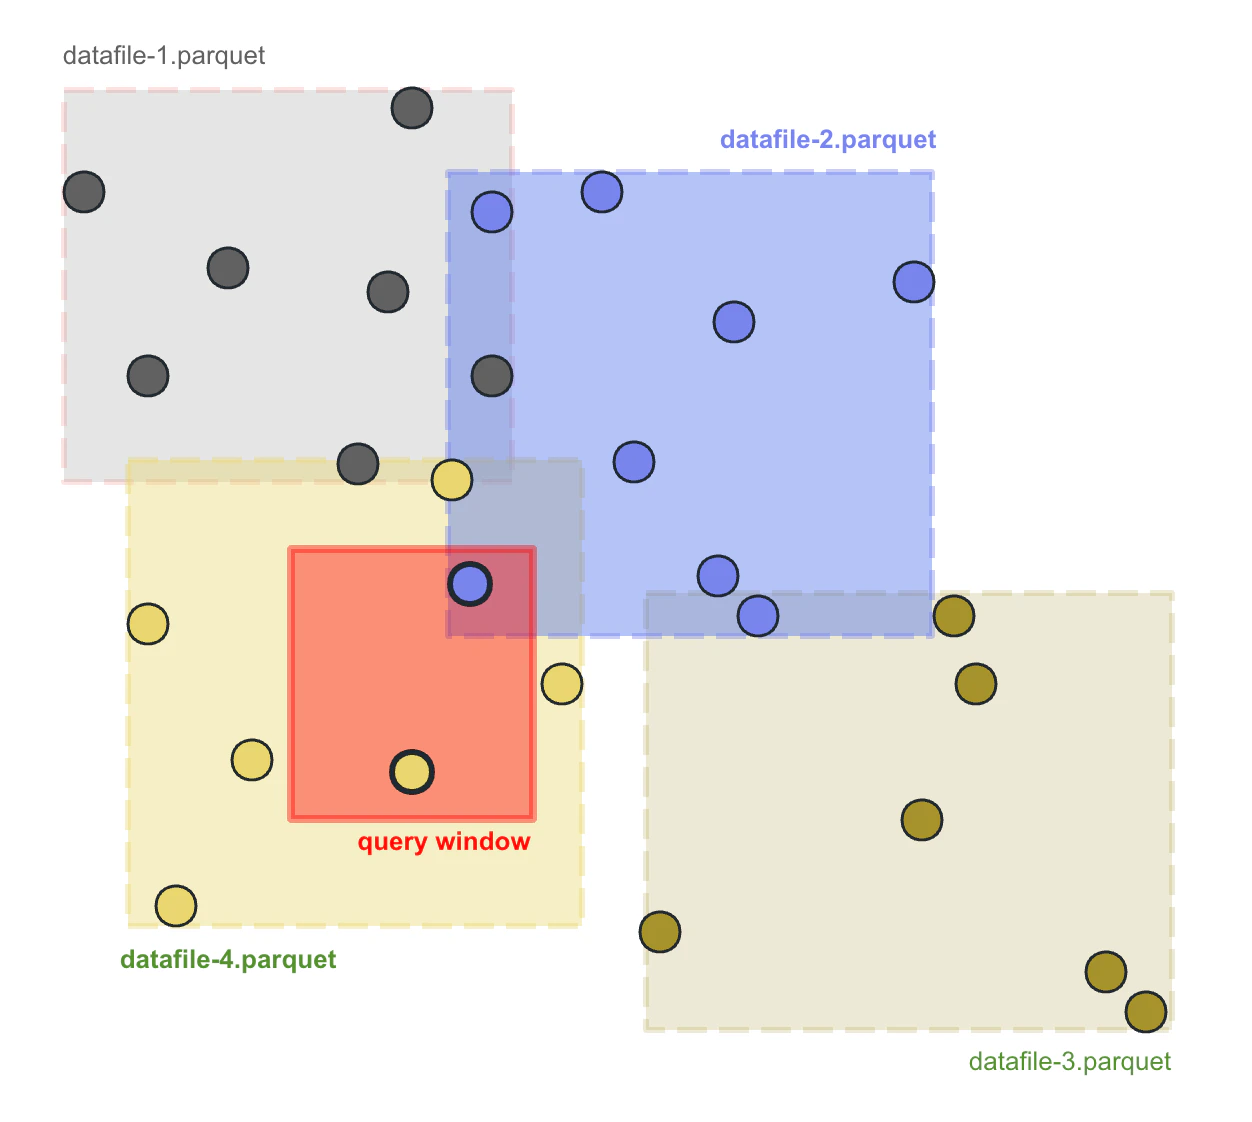
WherobotsDB keeps these statistics for a
geometry(<srid>) column in the standard Apache Iceberg column bounds. For a geometry column with no declared CRS and for a raster column, it keeps them only on format-version 1 and 2 tables, so for spatial filters on those columns it can’t skip data files on a format-version 3 table. See Spatial file skipping.CREATE SPATIAL INDEX, or partition it by a column related to location, as described in Other ways to cluster spatial data.
Raster columns
When WherobotsDB writes data files containing raster columns, it records the WGS84 bounding box of the rasters in each file. For raster spatial filters, such asRS_Intersects, RS_Contains, and RS_Within, it uses these bounds to skip unrelated data files. Push-down works for both in-db and out-db rasters.
Raster bounds are recorded only in Apache Iceberg format-version 1 and 2 tables, so WherobotsDB skips data files for raster filters only on those tables. New tables in Wherobots-managed catalogs, such as org_catalog, are format-version 3, so create a raster table that you filter spatially with TBLPROPERTIES ('format-version'='2'), as in Partitioning rasters by SRID. A format-version 2 table can’t have a GEOMETRY(<srid>) or GEOGRAPHY(<srid>) column.
Clustering with CREATE SPATIAL INDEX
WherobotsDB adds theCREATE SPATIAL INDEX statement, which rewrites the table so its rows are sorted by a geometry or raster column:
hilbert index strategy. hilbert sorts the data by the Hilbert index of the specified geometry field. Hilbert index is based on a space filling curve called Hilbert curve, which is very efficient at sorting geospatial data by spatial proximity. You can specify the precision of the hilbert curve using the precision parameter. The precision parameter is the number of bits used to represent the Hilbert index. The higher the precision, the more accurate the sorting will be.
The two-argument form,
hilbert(<geometry_column>, <precision>), clusters over World Geodetic System 1984 (WGS84) longitude and latitude bounds, [-180, 180] and [-90, 90]. On a geometry(<srid>) column the declared CRS is checked against those bounds, so the statement is rejected when the column is in another CRS. Pass <minX>, <minY>, <maxX>, <maxY> to cluster a column in another CRS, as described in Clustering a column that is not WGS84.org_catalog.test_db.test_table by the geometry column geom:
CREATE SPATIAL INDEX FOR is shorthand for calling the rewrite_data_files procedure:
OPTIONS clause passes any option of the rewrite_data_files procedure. For example, set the target file size to 10MB:
WHERE clause limits the rewrite to the data files that may contain matching rows. Every row in those files is rewritten, including rows that don’t match. For example, rewrite the data files that may hold rows with state = 'CA':
target-file-count option, as the CREATE SPATIAL INDEX statement will automatically determine the size of output data files based on the size of the table to balance the file size and the number of data files.
If the default behavior of CREATE SPATIAL INDEX is not desirable, you can specify the following options to control the number of data files:
target-file-count: The number of output data files. This option is useful when you want to rewrite the table to an expected number of data files. The exact number of data files may be different from the expected number due to various factors such as compression, heuristics for avoiding too large data files, etc.
Clustering a column that is not WGS84
Running the two-argument form on a column whose declared CRS is not WGS84 is rejected, and the message names both ways out:±20037508.34 meters on both axes, which is longitude ±180 and latitude ±85.0511:
±85.06, or ±20048966.10 meters.
Clustering by a raster column
CREATE SPATIAL INDEX also clusters a table by a raster column. For example, cluster the data in table org_catalog.test_db.test_table by the raster column rast:
- The original table does not have a good column for partitioning.
- The table contains out-db rasters or very small in-db rasters.
Other ways to cluster spatial data
BesidesCREATE SPATIAL INDEX, you can cluster spatial data by partitioning or sorting the table.
Partitioning by columns closely related to spatial property
If the data you are working with has at least one column that is closely related to the spatial property, it is usually a good idea to partition the table using that column. For example, if you are working with a table containing census data, and the data has astate column indicating the state ID of the data, you can partition the table by state:
state partition works well for both regular queries with filters such as state = 'some_state' and spatial queries with filters such as ST_Intersects(geom, <query_window>). For the former, WherobotsDB skips data files whose state partition doesn’t match the filter. For the latter, it skips data files using their spatial statistics.
The same applies to raster tables. For a table of rasters of different cities, partitioning by the city name column stores the rasters of each city in the same partition, so WherobotsDB skips more data files for raster filters.
Partitioning by spatial proximity
If your dataset does not have a field to directly partition by, you can partition the dataset by the S2 cell ID of the geometry. This requires selecting a proper S2 resolution level suited for your dataset.s2 column set to the S2 cell ID of the geometry, and the values in geom have to carry the SRID of the column, as described in Matching the column CRS:
- Python
- Scala
- Java
Partitioning rasters by SRID
When the rasters in a table are in Universal Transverse Mercator (UTM) coordinate reference systems spread over several UTM zones, partition the table by SRID. This example partitions the EuroSAT dataset by SRID, in a format-version 2 table so that raster bounds are recorded:- Python
- Scala
- Java
Sorting by GeoHash
You can sort the rows byST_GeoHash(<geometry_column>, <precision>) as you write them, to cluster the data by spatial proximity. Create the destination table first, with a geometry(<srid>) column:
df to hold WGS84 geometries with SRID 4326; for geometries in another CRS, or with SRID 0, see Matching the column CRS:
- Python
- Scala
- Java
CREATE SPATIAL INDEX FOR for sorting the table over manually sorting the table. CREATE SPATIAL INDEX FOR will use the Hilbert curve to sort the table, which is more efficient than sorting by GeoHash.
Related pages
Iceberg Tables Overview
Spatial file skipping on each format version.
Geometry and Geography Tables
Creating, writing, and querying geometry tables.
Raster Tables
Creating, writing, and querying raster tables.
Upgrade Existing Geometry Tables
Copy a table with no declared CRS into one whose geometry column keeps file skipping on format-version 3.